

详细内容
🎉 DeepSeek V3.1: DeepSeek's Latest Open Source AI Model →
DeepSeek v3: Advanced AI Language Model
DeepSeek v3 represents a major breakthrough in AI language models, featuring 671B total parameters with 37B activated for each token. Built on innovative Mixture-of-Experts (MoE) architecture, DeepSeek v3 delivers state-of-the-art performance across various benchmarks while maintaining efficient inference.
Try DeepSeek v3 Online Try Nano Banana →
DeepSeek v3 Capabilities
Explore the impressive capabilities of DeepSeek v3 across different domains - from complex reasoning to code generation
Key Features of DeepSeek v3
Discover what makes DeepSeek v3 a leading choice in large language models
- 🏗️
Advanced MoE Architecture
DeepSeek v3 utilizes an innovative Mixture-of-Experts architecture with 671B total parameters, activating 37B parameters for each token for optimal performance.
- 🎨
Extensive Training
Pre-trained on 14.8 trillion high-quality tokens, DeepSeek v3 demonstrates comprehensive knowledge across various domains.
- 💭
Superior Performance
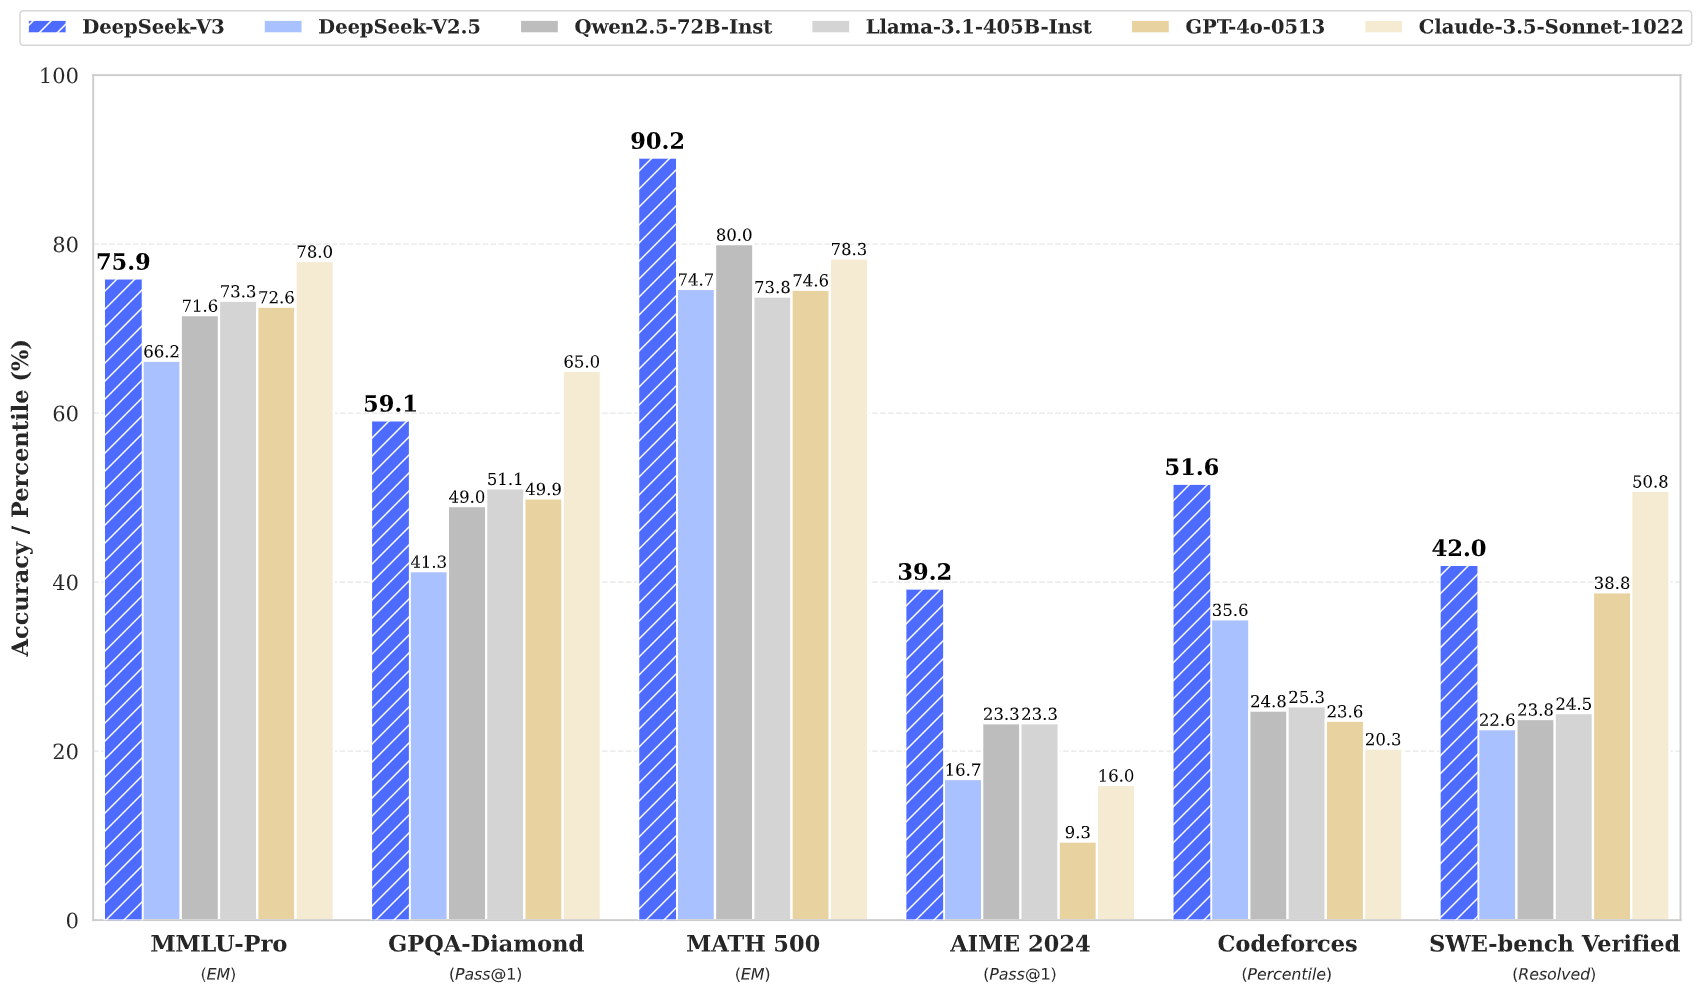
DeepSeek v3 achieves state-of-the-art results across multiple benchmarks, including mathematics, coding, and multilingual tasks.
- 🌐
Efficient Inference
Despite its large size, DeepSeek v3 maintains efficient inference capabilities through innovative architecture design.
- ✨
Long Context Window
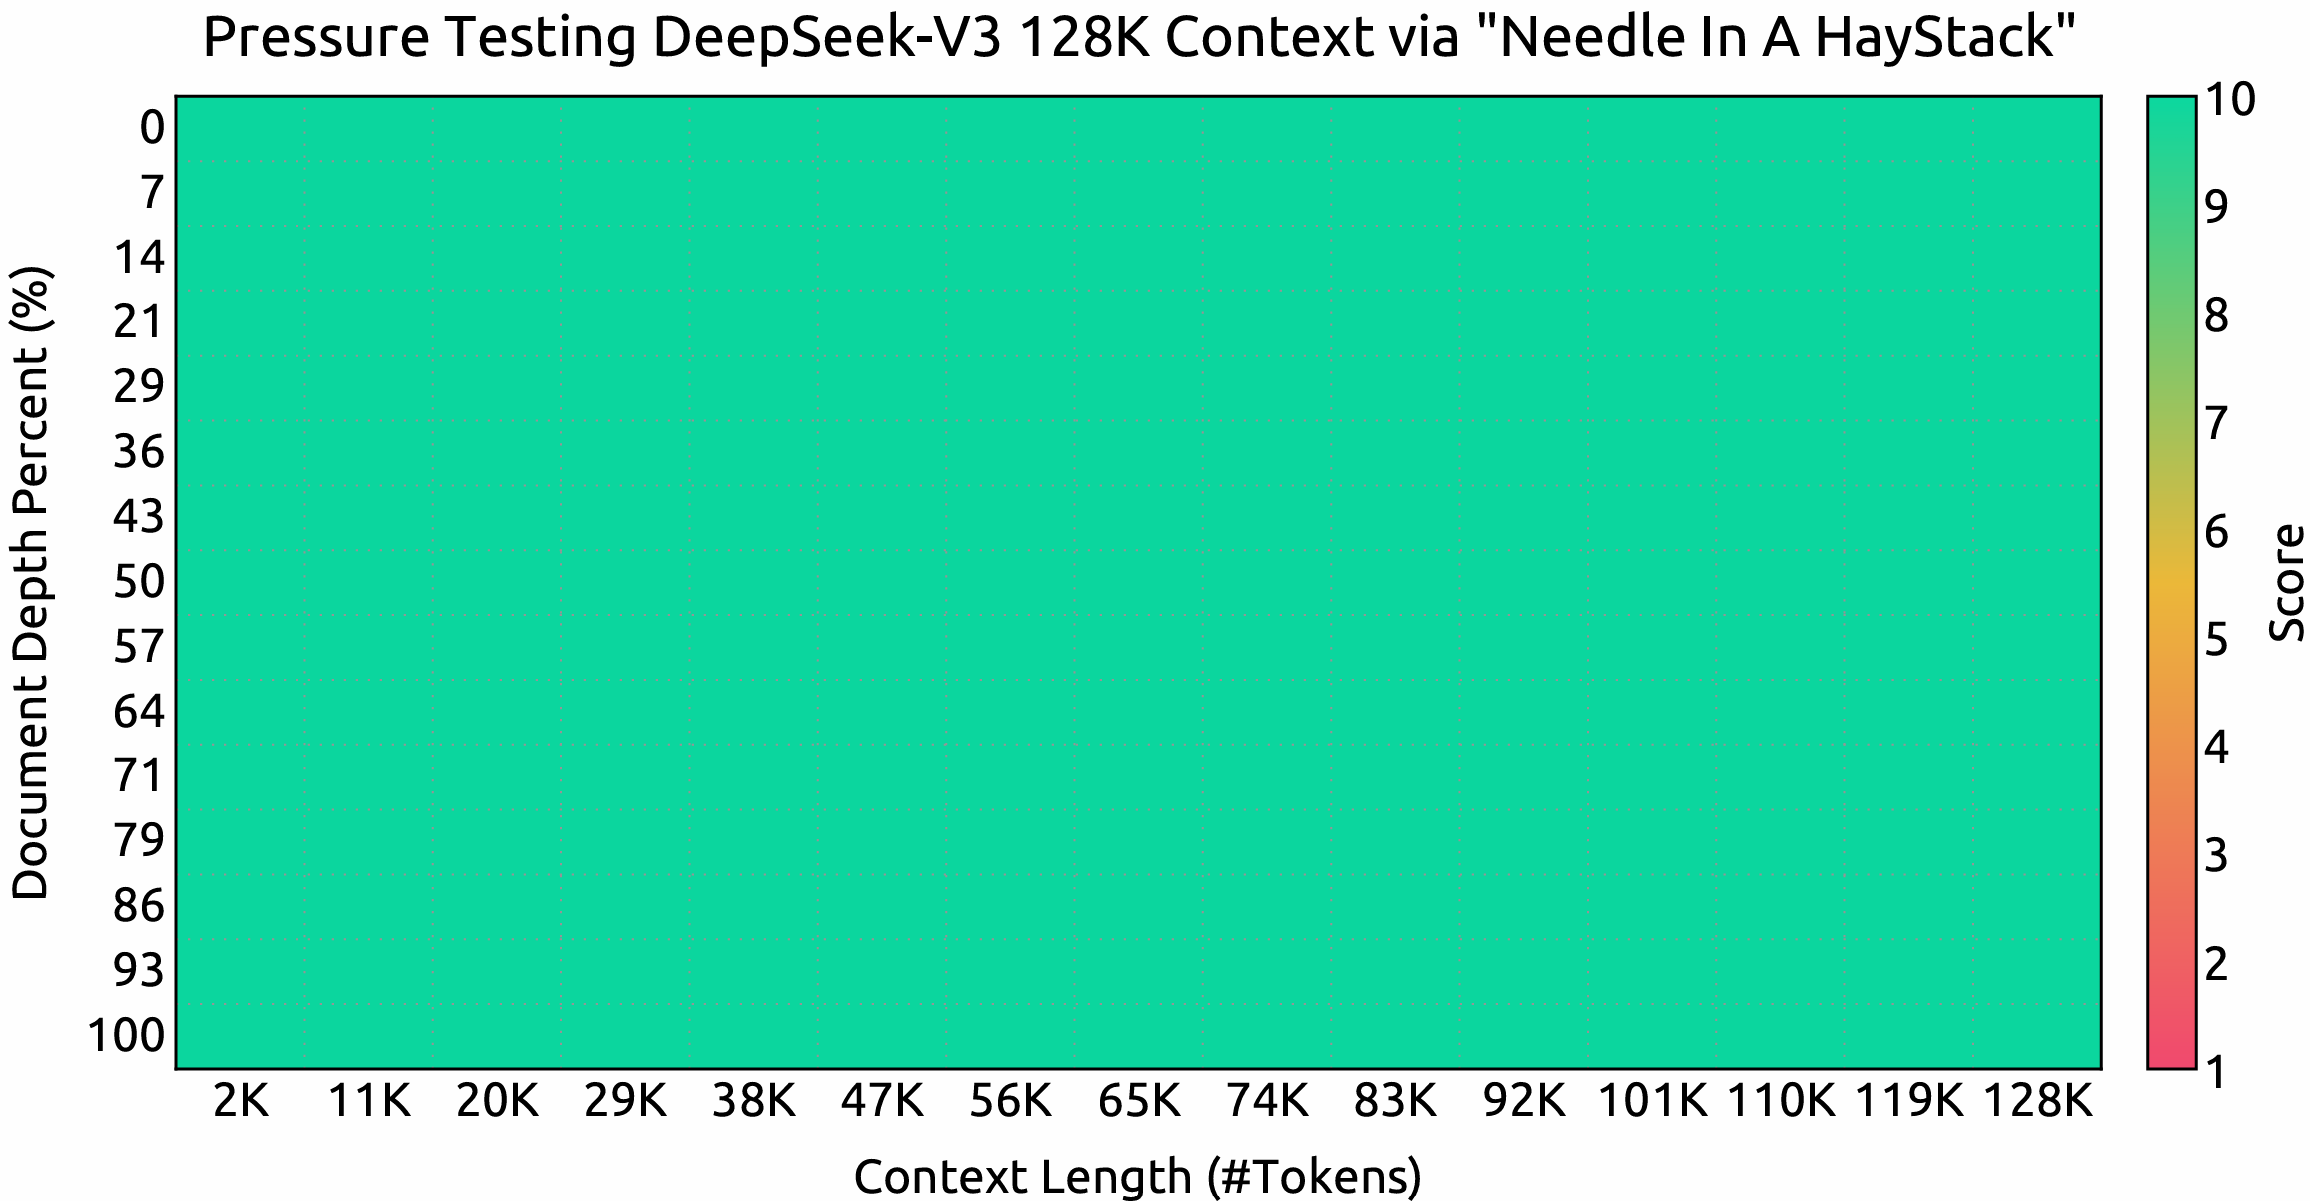
With a 128K context window, DeepSeek v3 can process and understand extensive input sequences effectively.
- ⚡
Multi-Token Prediction
DeepSeek v3 incorporates advanced Multi-Token Prediction for enhanced performance and inference acceleration.
How to Use DeepSeek v3
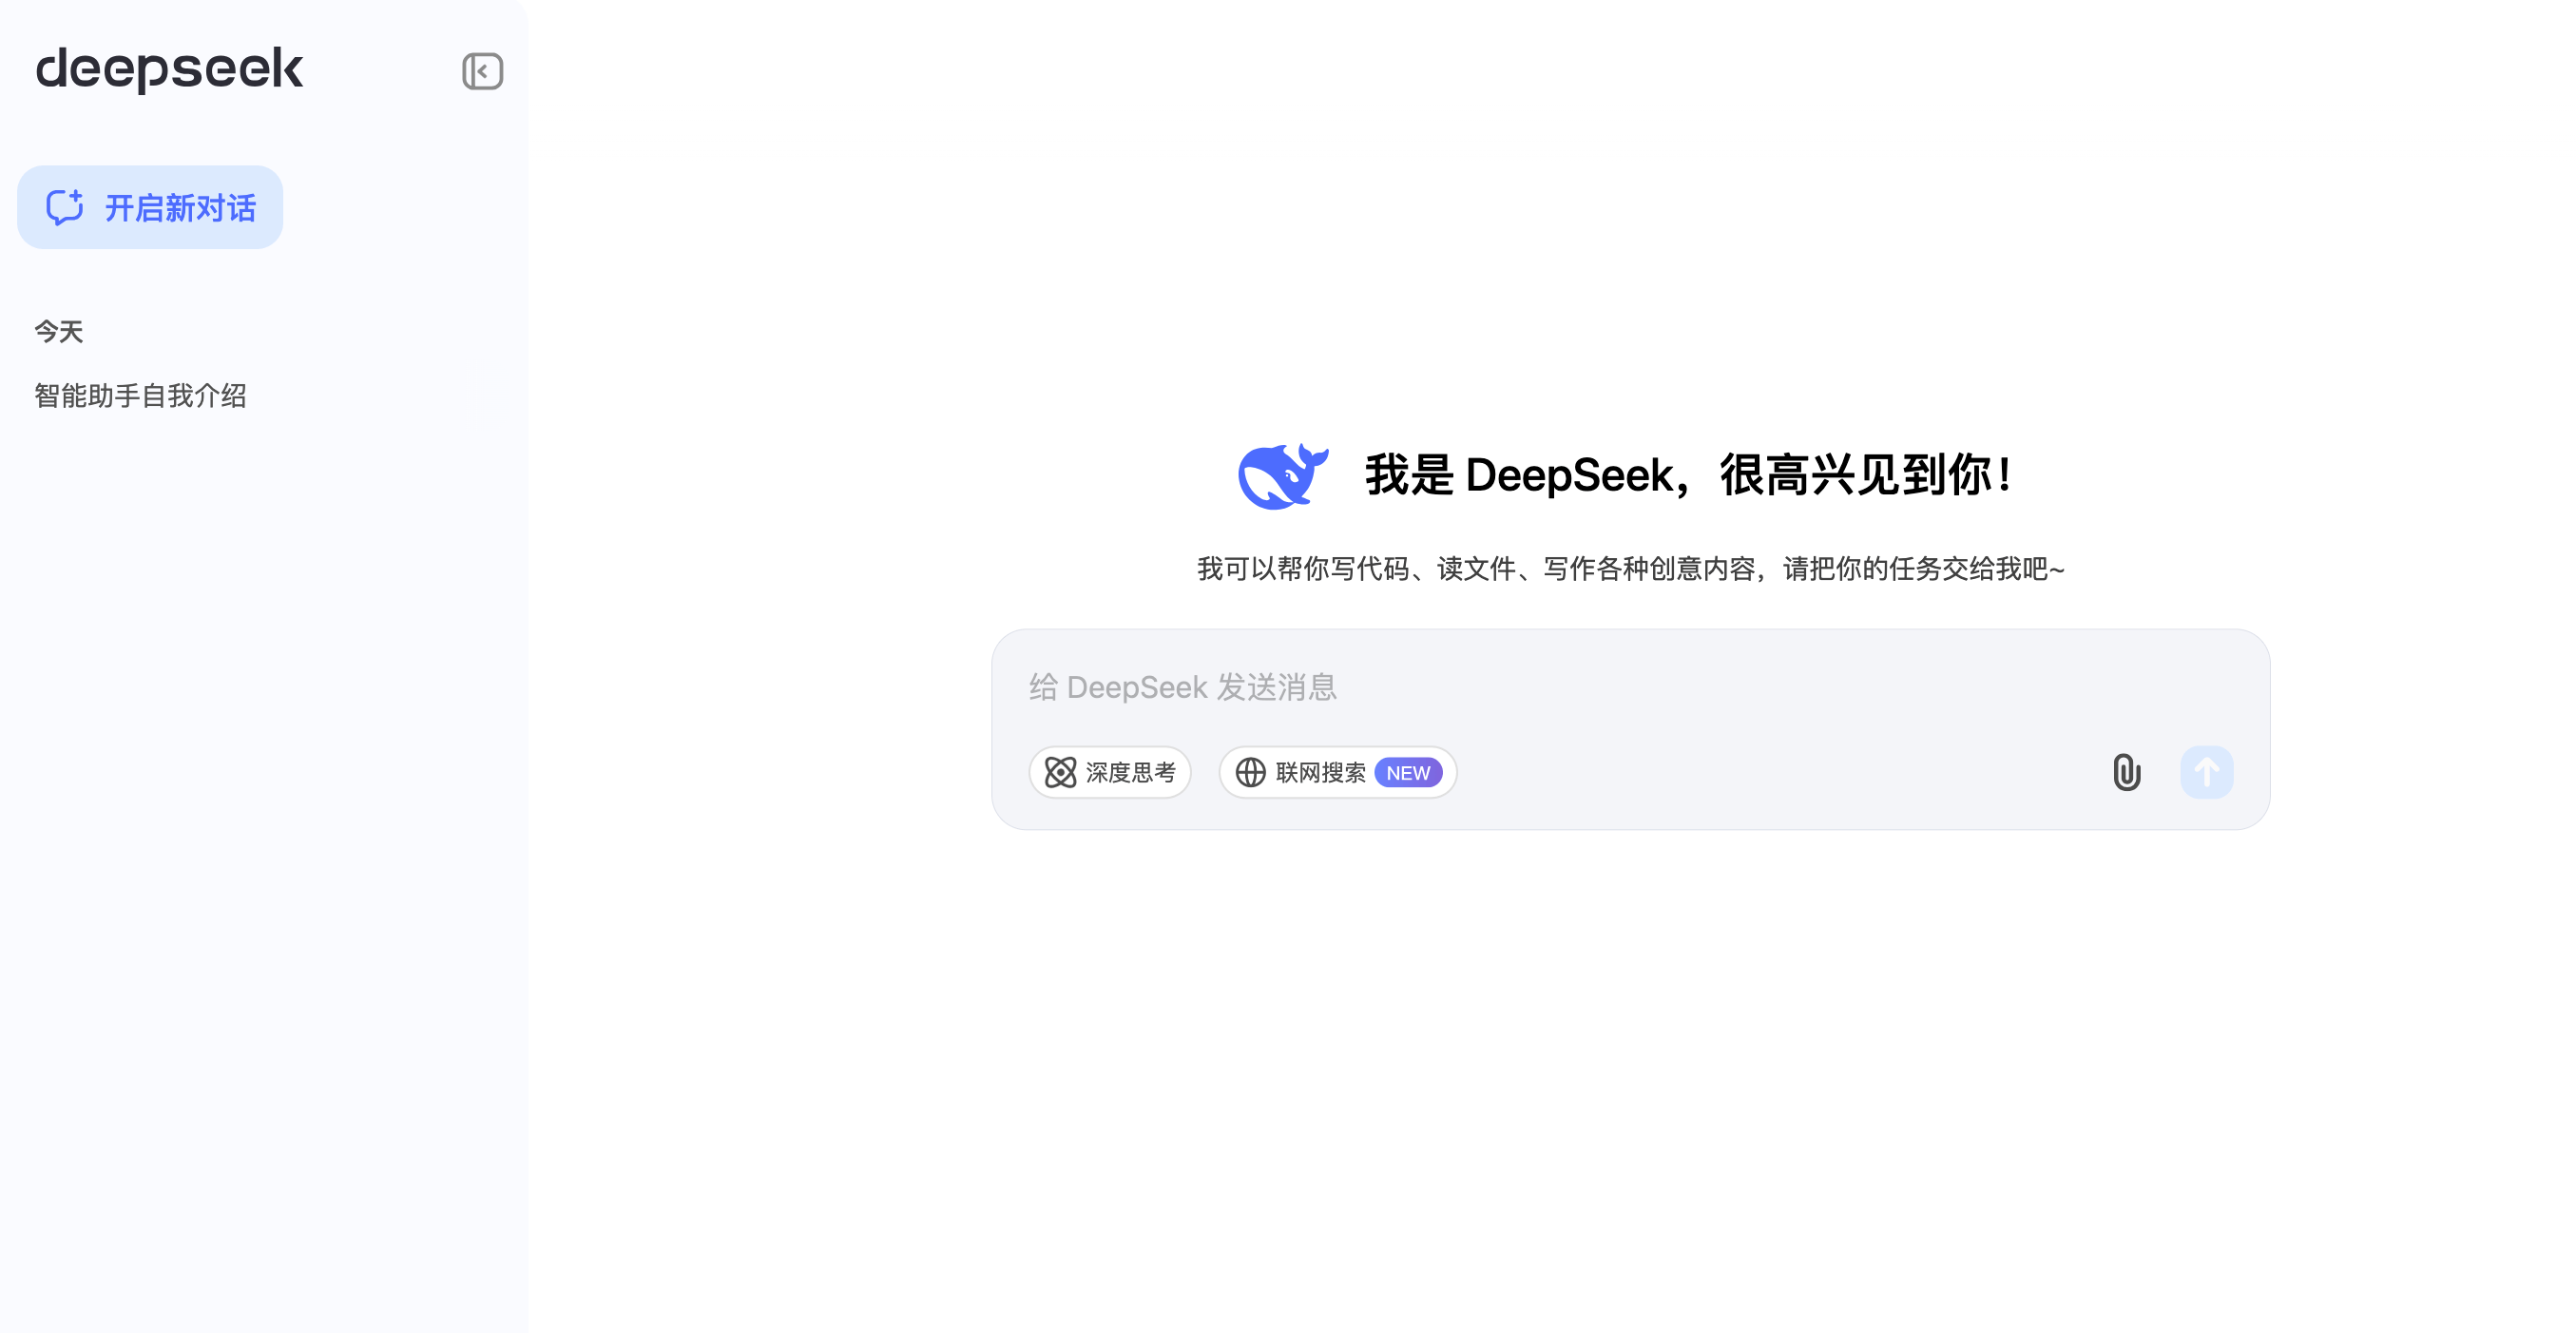
Access the power of DeepSeek v3 in three simple steps
-
Choose Your Task
Select from various tasks including text generation, code completion, and mathematical reasoning. DeepSeek v3 excels across multiple domains.
-
Input Your Query
Enter your prompt or question. DeepSeek v3's advanced architecture ensures high-quality responses with its 671B parameter model.
-
Get AI-Powered Results
Experience DeepSeek v3's superior performance with responses that demonstrate advanced reasoning and understanding.
What Experts Say About DeepSeek v3
Discover how DeepSeek v3 is advancing the field of AI language models

· Follow
🚀 Introducing DeepSeek-V3!
Biggest leap forward yet:
⚡ 60 tokens/second (3x faster than V2!)
💪 Enhanced capabilities
🛠 API compatibility intact
🌍 Fully open-source models & papers
🐋 1/n

6:26 AM · Dec 26, 2024 Twitter for Websites, Ads Information and Privacy
Copy link

· Follow
Wait, so we now have a 100% open source model that's better than GPT-4o?!
DeepSeek v3 is even superior to Claude Sonnet 3.5 for code according to multiple benchmarks.
Already available for free to everyone 🧵

11:34 AM · Dec 26, 2024 Twitter for Websites, Ads Information and Privacy
Copy link

· Follow
China trained a model called DeepSeek-v3 that’s better than OpenAI GPT 4o with a small fraction of the budget and open sourced it. Meanwhile, a bipartisan bill is in the works in America to impose severe restrictions on open sourcing frontier models.
DeepSeek
@deepseek_ai
🚀 Introducing DeepSeek-V3!
Biggest leap forward yet:
⚡ 60 tokens/second (3x faster than V2!)
💪 Enhanced capabilities
🛠 API compatibility intact
🌍 Fully open-source models & papers
🐋 1/n
10:56 PM · Dec 26, 2024 Twitter for Websites, Ads Information and Privacy
Copy link

· Follow
DeepSeek-V3 is officially out!
- 671B MoE
- 60 tokens/second (3x faster than V2!)
- Fully open-source 🔥
6:39 AM · Dec 26, 2024 Twitter for Websites, Ads Information and Privacy
Copy link

· Follow
It is quite fitting that DeepSeek, China’s leading LLM lab, releases its latest model V3 on Christmas.
- on-par with GPT-4o & Claude 3.5 Sonnet
- trained w/10x less compute
The bitter lesson of Chinese tech: they work while America rests, and catch up cheaper, faster & stronger

DeepSeek
@deepseek_ai
🚀 Introducing DeepSeek-V3!
Biggest leap forward yet:
⚡ 60 tokens/second (3x faster than V2!)
💪 Enhanced capabilities
🛠 API compatibility intact
🌍 Fully open-source models & papers
🐋 1/n
12:37 PM · Dec 26, 2024 Twitter for Websites, Ads Information and Privacy
Copy link
Latest Blog Posts
Stay updated with the latest news and insights from the DeepSeek v3
 \
\
DeepSeek V3.1 - A Comprehensive Analysis of the Latest Open-Source AI Model\
\
DeepSeekAI ModelV3.1Open SourceLarge Language Model\
\
August 20, 2025  \
\
DeepSeek-V3-0324 Update - Comprehensive Upgrades Across All Capabilities\
\
DeepSeekAI UpdateV3-0324Open Source\
\
March 25, 2025 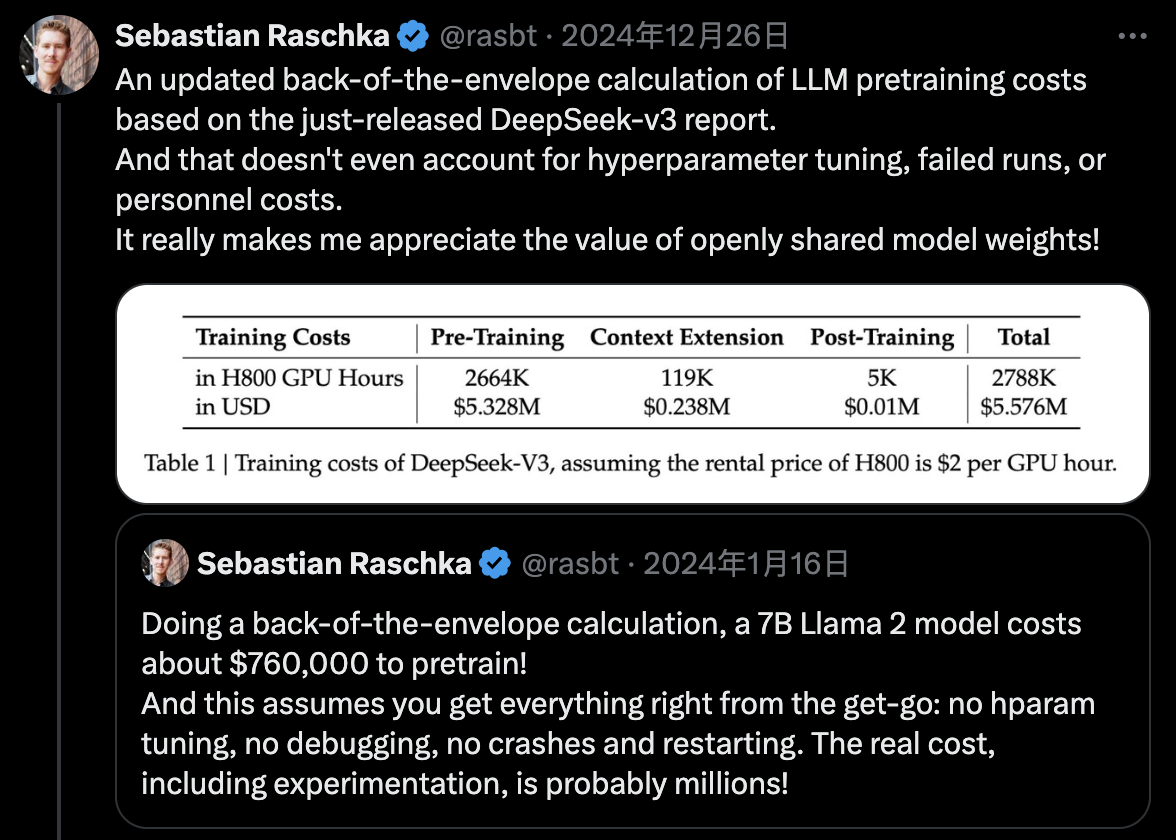 \
\
DeepSeek V3 - Redefining AI Efficiency Standards\
\
DeepSeekAIEfficiencyMoE\
\
January 13, 2025
About DeepSeek v3
DeepSeek v3 represents the latest advancement in large language models, featuring a groundbreaking Mixture-of-Experts architecture with 671B total parameters. This innovative model demonstrates exceptional performance across various benchmarks, including mathematics, coding, and multilingual tasks.
Trained on 14.8 trillion diverse tokens and incorporating advanced techniques like Multi-Token Prediction, DeepSeek v3 sets new standards in AI language modeling. The model supports a 128K context window and delivers performance comparable to leading closed-source models while maintaining efficient inference capabilities.
💻 deepseek v3 github 🎮 deepseek v3 huggingface
DeepSeek v3 Frequently Asked Questions
-
What makes DeepSeek v3 unique?
DeepSeek v3 combines a massive 671B parameter MoE architecture with innovative features like Multi-Token Prediction and auxiliary-loss-free load balancing, delivering exceptional performance across various tasks.
-
How can I access DeepSeek v3?
DeepSeek v3 is available through our online demo platform and API services. You can also download the model weights for local deployment.
-
What tasks does DeepSeek v3 excel at?
DeepSeek v3 demonstrates superior performance in mathematics, coding, reasoning, and multilingual tasks, consistently achieving top results in benchmark evaluations.
-
What are the hardware requirements for running DeepSeek v3?
DeepSeek v3 supports various deployment options including NVIDIA GPUs, AMD GPUs, and Huawei Ascend NPUs, with multiple framework options for optimal performance.
-
Is DeepSeek v3 available for commercial use?
Yes, DeepSeek v3 supports commercial use subject to the model license terms.
-
How does DeepSeek v3 compare to other language models?
DeepSeek v3 outperforms other open-source models and achieves performance comparable to leading closed-source models across various benchmarks.
-
What frameworks are supported for DeepSeek v3 deployment?
DeepSeek v3 can be deployed using multiple frameworks including SGLang, LMDeploy, TensorRT-LLM, vLLM, and supports both FP8 and BF16 inference modes.
-
What is the context window size of DeepSeek v3?
DeepSeek v3 features a 128K context window, allowing it to process and understand extensive input sequences effectively for complex tasks and long-form content.
-
How was DeepSeek v3 trained?
DeepSeek v3 was pre-trained on 14.8 trillion diverse and high-quality tokens, followed by Supervised Fine-Tuning and Reinforcement Learning stages. The training process was remarkably stable with no irrecoverable loss spikes.
-
What makes DeepSeek v3's training efficient?
DeepSeek v3 utilizes FP8 mixed precision training and achieves efficient cross-node MoE training through algorithm-framework-hardware co-design, completing pre-training with only 2.788M H800 GPU hours.
🇪🇸 Español 🇨🇳 繁體中文 🇨🇳 简体中文 🇫🇷 Français 🇯🇵 日本語 🇰🇷 한국어 🇮🇹 Italiano 🇩🇪 Deutsch 🇵🇹 Português 🇷🇺 Русский 🇸🇦 العربية 🇮🇳 हिन्दी 🇮🇩 Indonesia